MetArenaStats
Case Study · Web & Data
Tier lists for a League of Legends game mode that no stats site covers properly. Built end to end on the Riot API.
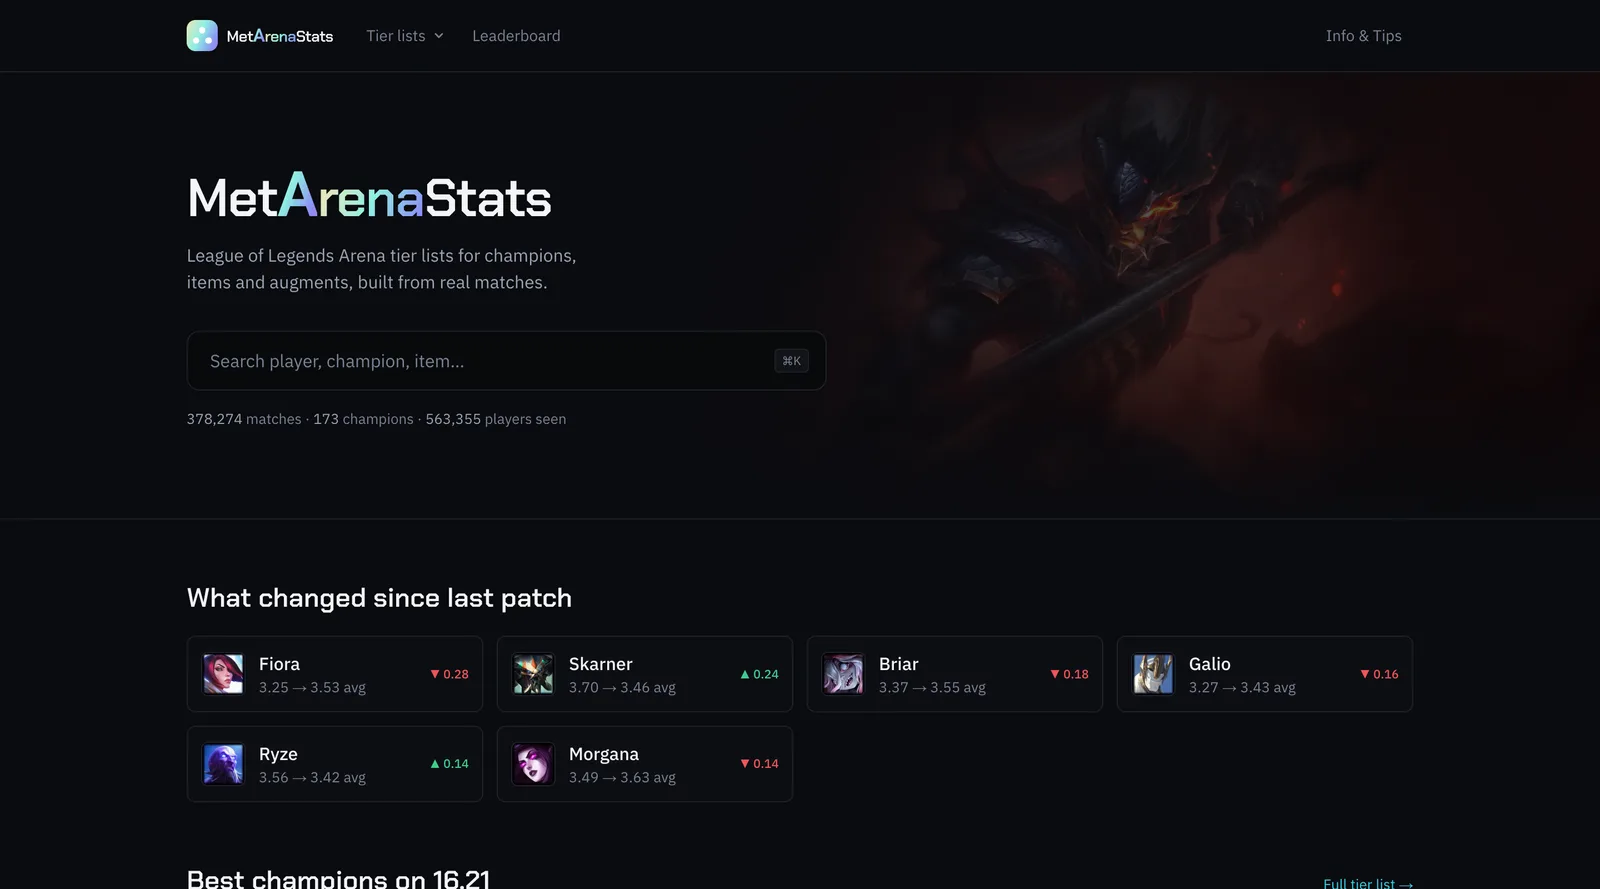
Code figures from the end of September 2026. The crawler is still running.
The problem
Arena is League of Legends' 3v3 mode: six teams of three, a shared pool of augments and prismatic items that exist nowhere else in the game, and a placement from 1st to 6th instead of a win or a loss.
The popular stats sites are all built for Summoner's Rift. They report win rates, which Arena doesn't have, and there is almost no public data on augments, which decide most Arena games. Players pick from a three-way choice, several times a game, on feel.
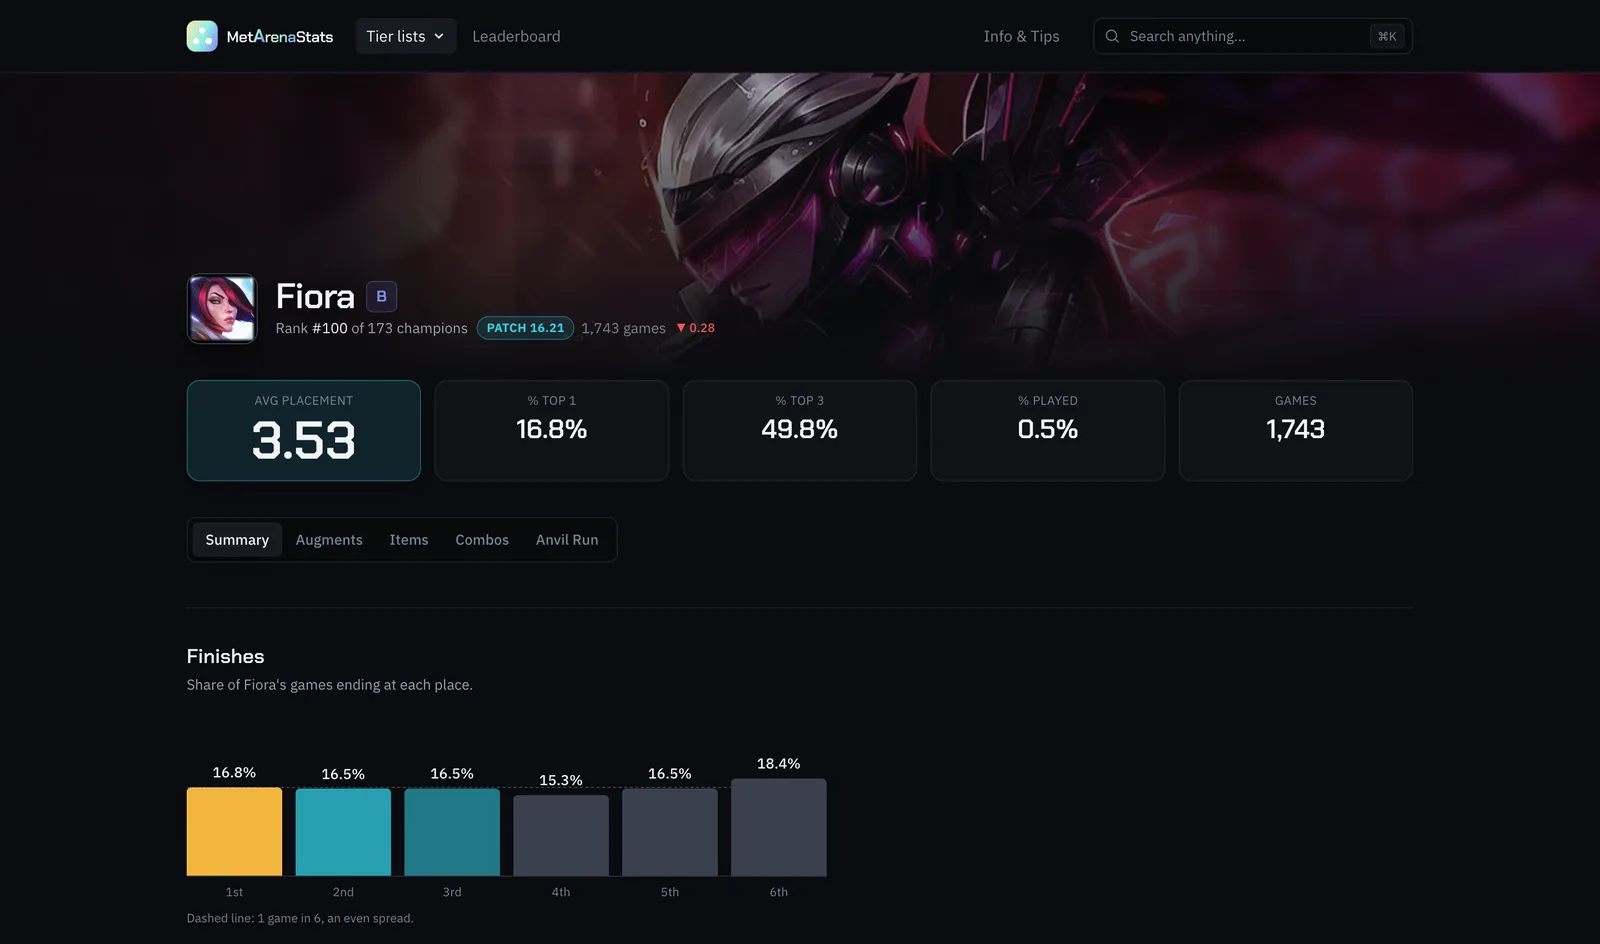
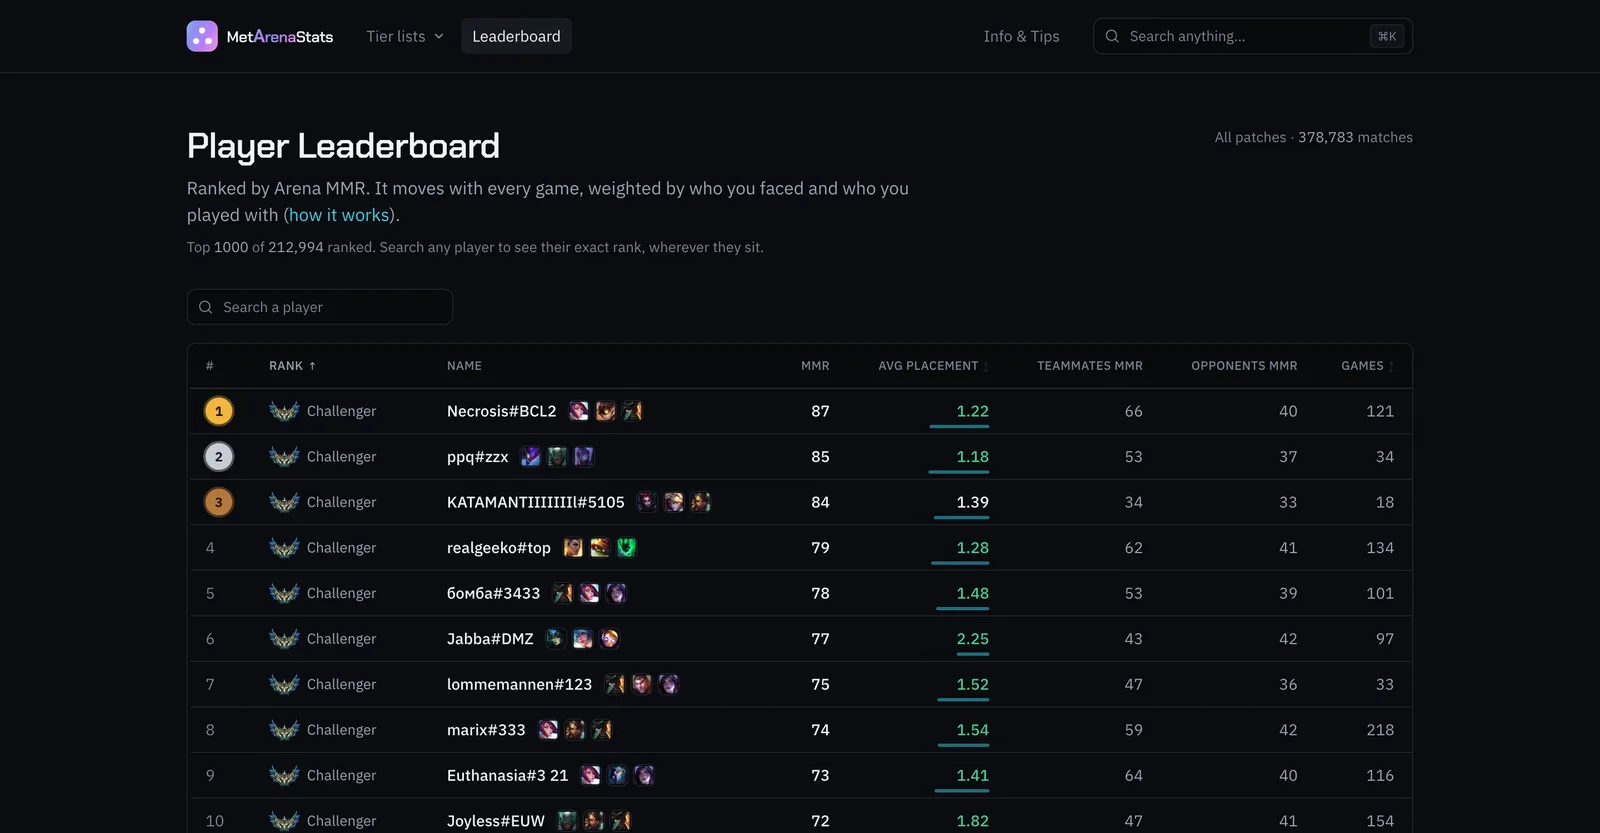
MetArenaStats covers what Arena players need to know: which champions place well, which augments are worth taking, which items to build, and which comps place together. Everything is ranked on average placement, patch by patch. Riot doesn't expose an Arena ranking either, so the site computes its own rating and gives the mode a leaderboard it didn't have.
The stack
Frontend & rendering
Next.js 16 · React 19 · TypeScript
Stats pages serve a precomputed snapshot, regenerated every 30 minutes. Only player pages are dynamic, because they hit the Riot API live.
Database
Supabase (Postgres)
Matches, a crawl queue and the stat snapshots. Most of the aggregation runs in SQL functions, recomputed every hour.
Data collection
Riot Games API · GitHub Actions
A crawler running as a long-lived GitHub Actions job. Runner minutes are free on a public repo, so the limit is the API key.
Hosting & delivery
Vercel · Cloudflare DNS
Deployed from main, served at metarenastats.tblabs.dev, with
the refresh jobs behind a shared secret.
Working the Riot API
This is where most of the work went. The API has a strict rate limit, and its data doesn't always match the documentation.
The rate limits are in the response headers
Riot returns the live state of every counter in the headers of every response:
x-app-rate-limit:       100:120,20:1   ← the key: 100 req/2min AND 20 req/s
x-app-rate-limit-count: 3:120,1:1      ← where we currently stand
x-method-rate-limit:    2000:10        ← this endpoint only
Watching them turned up something the portal doesn't mention:
the counter is per regional host. The europe
host and the euw1 host are two independent budgets, so anything
served from the second one costs nothing against the match budget. That
changed what was worth building.
Every call goes through a limiter that retries when Riot says to wait, so no match gets dropped silently. That fix had a side effect: under load, a visitor's search could take two minutes. A blank page for two minutes is worse than a clean error, so searches now give up after 15 seconds with a clear message, while the crawler, which has nobody waiting on it, is allowed to sit and wait.
How the crawler finds matches
Take a player from the queue and fetch their Arena match IDs.
Keep only the ones the database doesn't have. Calls are only spent on new matches.
Fetch the match, store its 18 participants, and push the 17 other players into the queue.
Repeat. Every match brings in new players, so the queue never runs dry. It went from 300 players to hundreds of thousands this way.
Item order is not build order
A match returns each player's item0…item6, which looks like build
order but is the order of the inventory slots. Cross-checked against
a second endpoint on 4,363 players, the first slot was the first
purchase only 37.5% of the time, so two thirds of my first "first
item" stat was noise.
That second endpoint has a gap of its own: prismatic items never appear in it, because they don't come from the shop. So the site keeps both sources, one for purchase order and one for prismatics, and says which is which.
A misleading statistic
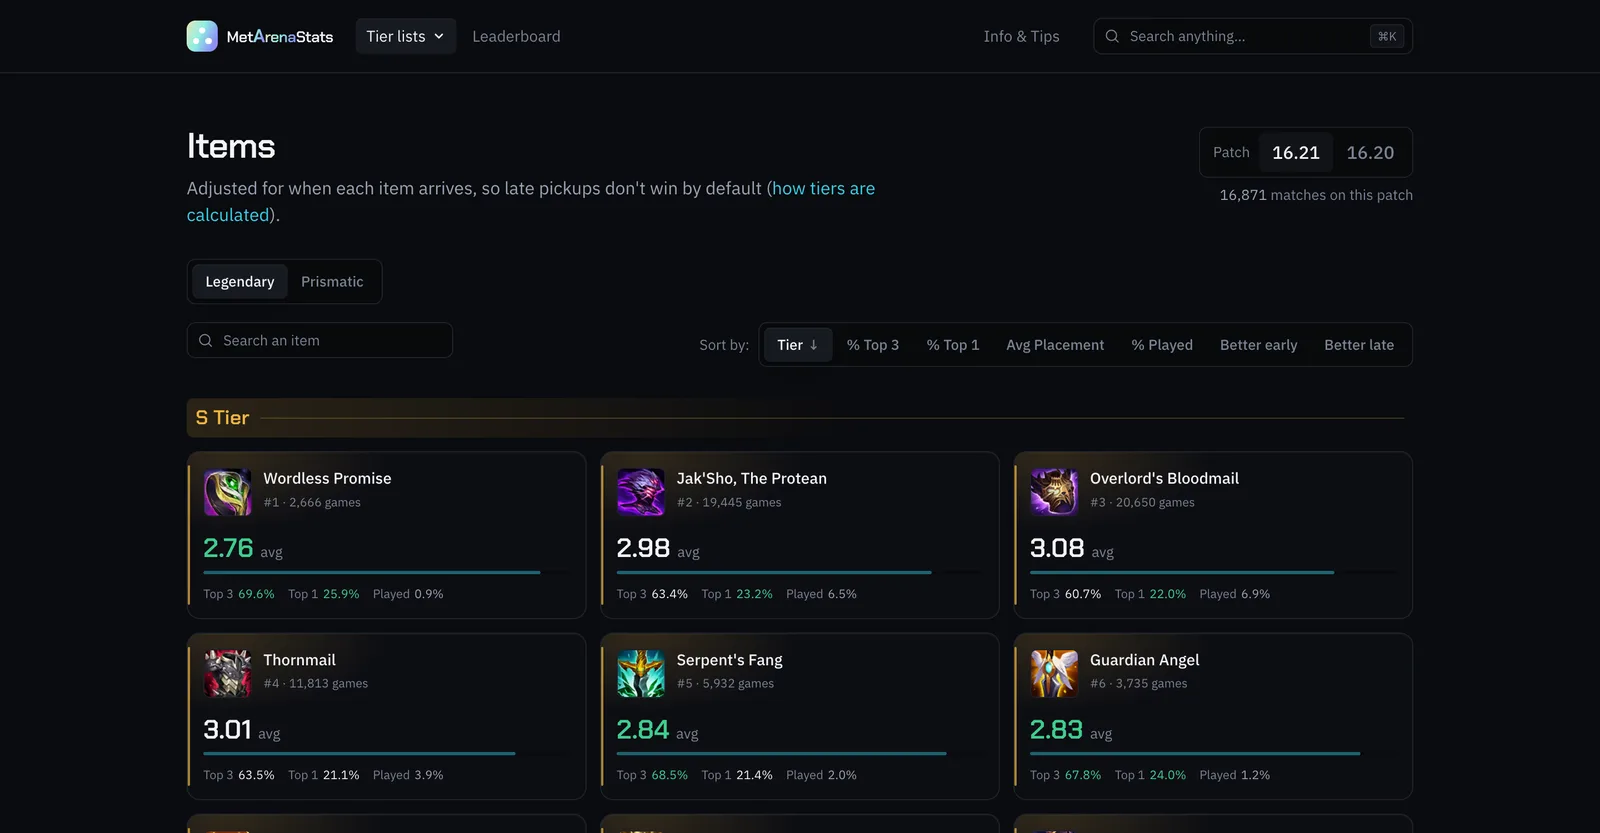
At first, late-game items looked like the strongest in the mode. The cause was game length: a sixth item only exists in a game that lasted long enough to buy six: players who bought three items averaged 3.90, players who bought six averaged 2.48, whatever the items were.
So an item's tier now compares it only with purchases made at the same point in the build, by players of similar level. The "Avg Placement" column still shows the raw average, so it matches what happened in games. The correction is partial, and the site's info page says so.
Three decisions, with the numbers behind them
Each one started with a measurement.
Stop recomputing everything on every page view
Every stats page loaded the whole table and aggregated it on the fly. A page view cost 3.7 MB of database traffic, and a hard-coded cap meant the numbers would have gone silently wrong as the data grew. Everything is now computed once an hour and stored, and if a read comes back incomplete, the job fails and nothing is published.
The rewrite that a row count cancelled
The obvious next step was to pre-aggregate everything in the database. I counted first: the groups it would produce (champion pairs, item combinations) came to 17 times more rows than the raw data. The rewrite was dropped before it was written. Ten days and a lot more data later the same count came out the other way for part of it, and only that part moved.
Finding the real bottleneck
GitHub's scheduler was firing 6 times in 16 hours instead of 16, and no setting fixes that. So one trigger now runs for hours instead of minutes. Runner time is free and unlimited, while the Riot key is limited and shared with visitors searching their own name. I had been optimising the wrong one.
The longer version, with the disk that filled up, the rating model and the things that broke along the way, is in the pipeline journal in the repo.
How it was built: iterating with Claude Code
I'm not a developer by trade. MetArenaStats was built by directing an AI coding agent, Claude Code, over roughly 230 commits in under four weeks. The agent writes the code. Here is how I worked with it.
Keep the record, including what went wrong
The pipeline is documented in a dated journal next to the code. When reality disagrees with it, the original design stays and the correction goes underneath with the measurement that forced it. It's what stops an agent with no memory of last week from proposing an idea that was already tested and rejected.
Measure first, then let it write
An agent will happily implement any plausible plan you hand it, so nothing gets optimised before it has been measured. Choosing which plan to implement is my job.
Define what "it works" means before starting
Moving a computation must not change a number that's already published. So each refactor is checked by running the old and the new code on identical data and comparing the output. On the first one, 181 of the 182 results came out identical, the 182nd being the one that was meant to change.
Own the product decisions
The crawler uses about a quarter of the Riot key on purpose, because the rest belongs to visitors. That is a product decision, so it is written down in the repo where no agent will change it by accident.
Why I build these
I'm a functional consultant moving into Solutions Engineering, Pre-Sales and AI Deployment. Projects like this one are how I keep the technical half of that job hands-on: checking what an API returns, estimating what a design costs before building it, and explaining both to the people who have to decide.